Prepare a CSV table with a header row, one record per row and a clear key column. A dataset can represent stores, departments, categories or contributors—not only a list of people.
Recommended structure
- Save as a comma-separated .csv file.
- Use short, descriptive column headers.
- Keep one record per row and one value per cell.
- Choose a key column with a unique, nonblank value for each record.
- Include only columns useful for the intended lookup, tagging or display.
Keeping the table to around six useful columns makes it easier to manage; this is a recommendation, not a universal six-column limit.
Example store dataset
| StoreID | Store | Region |
|---|---|---|
| S001 | Central | North |
| S002 | Riverside | South |
In this example, StoreID is the unique key. Store and Region are related values belonging to the same row.
Clean up before uploading
Remove blank rows, duplicate keys, repeated header rows and irrelevant notes. Preserve identifiers such as 00125 as text so a spreadsheet does not remove leading zeroes. Check accented characters and punctuation in the exported CSV.
Create and review the dataset
Open Datasets → Create a New Dataset in Studio. Upload the CSV, review the preview, confirm the headers and select the intended key column using the controls shown. Resolve any validation messages before saving.
Use it in a project
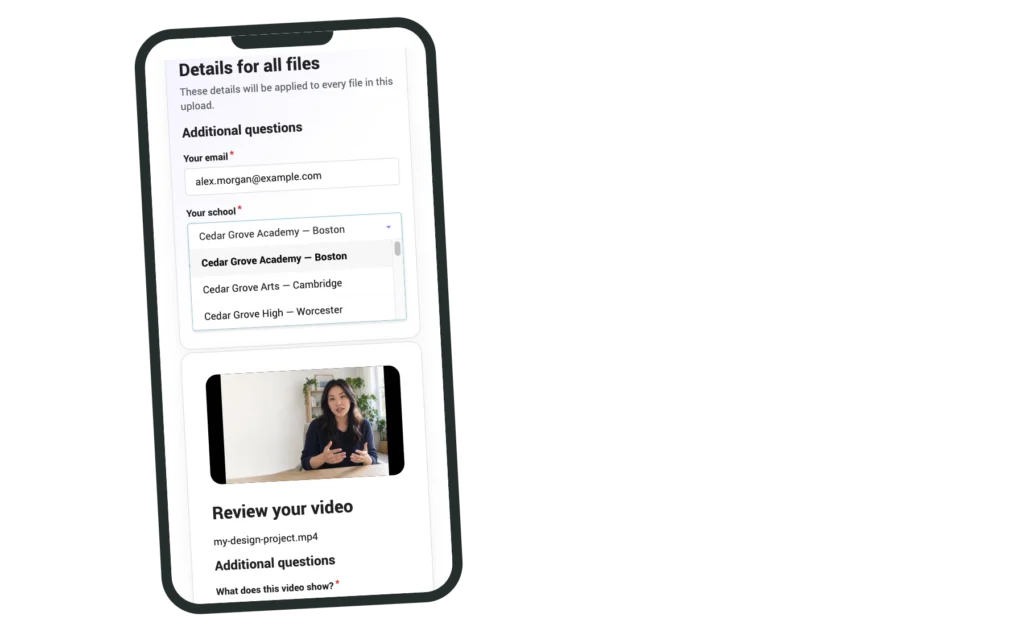
Under Collect → Contributor Data, add a structured question and link the dataset. Choose the appropriate column and review how contributors select or enter a value. Add tagging or dynamic video fields only where needed.
Keep the dataset appropriate for its audience
Use non-sensitive reference data where possible. A searchable field is not authentication and should not be treated as a guarantee that other records cannot be discovered.
Continue with linking a dataset to a contributor question.